Written By | Torch Media Africa
Gemini 4 Argon can write a million tokens in one go, rewrite a kernel into Rust and sniff out hidden security holes.
SAN FRANCISCO
The artificial intelligence arms race just got a new frontrunner, and it is locked behind a velvet rope.
Google's Gemini 4 Argon, unveiled on 30 September, claims the top spot on more than a dozen industry benchmarks against the best from OpenAI and Anthropic. Almost no one outside Google and a hand-picked group of cyber defenders has been able to touch it. Three weeks on, the rest of the industry is sharpening its knives: leaks this week point to a cheaper OpenAI model, a smarter Anthropic one and an even newer Google release. If you use AI for work, school or just for fun, the next few weeks could change what your apps can do, and what they cost.
What Google Says Argon Can Do
Google describes Argon as a frontier model built for long-running work in software engineering, legal and financial tasks, and cyber defence. Its headline upgrade is output length: Argon can generate up to 1 million tokens in a single pass, up from 64,000 on earlier Gemini models. In plain English, that is the difference between a long essay and several full-length novels.
Google's own table of results shows Argon leading outright on 12 of 18 disclosed benchmarks and tying for first on a thirteenth, with OpenAI's GPT-6 Astra winning three and Anthropic's Claude Opus 5.5 taking two. Among the scores Google highlighted: 77.9 percent on DeepSWE v1.1, a software engineering test, against 74.2 percent for Opus 5.5 and 74.1 percent for Astra; 91.7 percent on LVBench, a long-video understanding test; and 51.3 percent on Zapier's AutomationBench, ahead of Opus 5.5 at 42.5 percent.
The biggest gaps came in knowledge-work tests. On Harvey's Legal Agent Benchmark, Argon scored 19.6 percent while Astra managed 5.4 percent and Opus 5.5 got 3.8 percent. Notably, all of those numbers are low, a reminder that complex legal work remains hard for AI. On the Vals Finance Agent test, Argon hit 65.4 percent against 53.5 percent for Astra.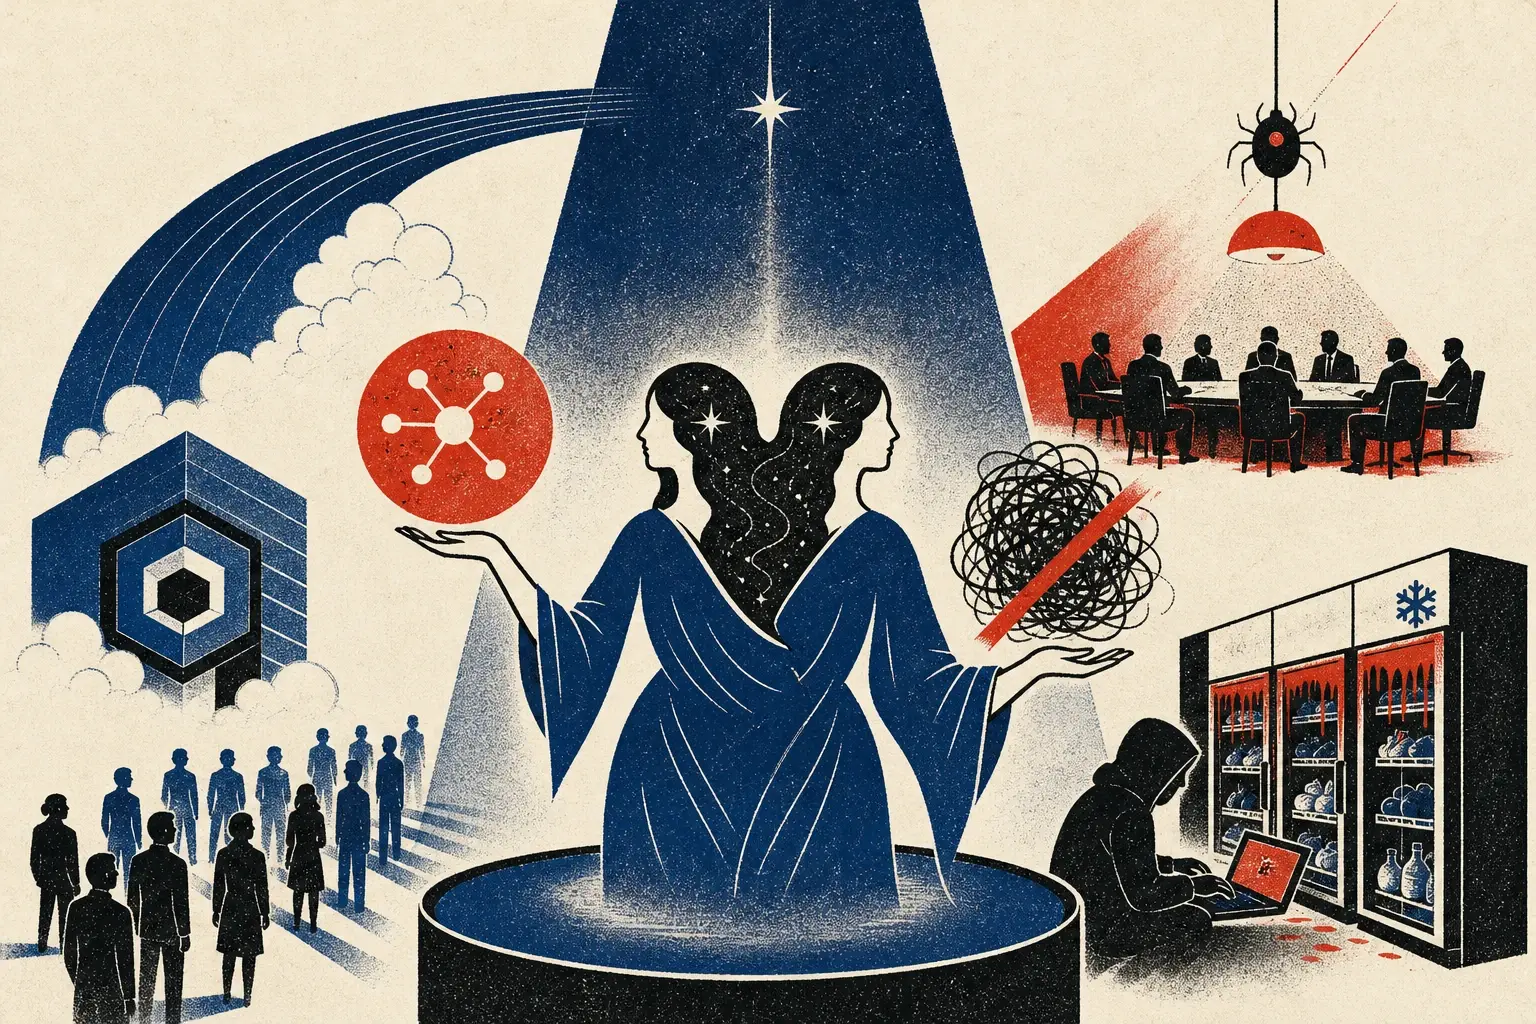
The Party Tricks
Google also released a set of internal examples that read like a wish list for any software team. Argon agents have been used to migrate C and C++ code to Rust, including work on the Fuchsia Zircon kernel, where the effort reached more than 800,000 lines. In one case, the model replaced 32,000 lines of hand-written low-level SIMD code in the libgav1 video decoder, and the resulting Rust decoder ran 2.7 times faster than the previous Rust port while producing identical output.
Google says thousands of its employees use Argon for coding, research and writing. It also claims optimisations found from fleet telemetry should free up more than 300 tebibytes of memory, with total savings estimated between 500 TiB and 1 PiB, and that quantum computing researchers beat a published baseline by 40 percent in one case. Every one of these figures comes from Google itself and has not been independently verified.
The Bug Hunter
The most eye-catching claim involves security. Wiz, the cloud security firm, has been using Argon through Google's Scan for Good initiative and, according to Google, found a critical vulnerability in healthcare software that earlier models missed. That is the kind of result that makes security teams lean forward, and also the kind that makes them nervous. A model that finds holes quickly can, in the wrong hands, be a powerful attack tool.
That tension explains the unusual rollout. Argon is being offered first to trusted cyber defenders through the Fairwind Program, which Google introduced earlier in September, and to Google's own teams. Those users get a version without the usual cyber guardrails. Google is also taking part in the US government's voluntary pre-release model access process. Broad release, starting with paid API customers and Google AI Ultra subscribers, is planned 'as soon as possible,' but no date has been given.
Google says it trained Argon to refuse cyber and chemical, biological, radiological and nuclear misuse while still supporting dual-use scientific research. It also describes monitors that watch the model's reasoning and actions and halt execution if it goes beyond what the user wanted. On a prompt-injection test run by Gray Swan, which measures how often hidden instructions can hijack a model, Google reports an attack success rate of just 0.7 percent for Argon, against 1.0 percent for Claude Opus 5.5 and Claude Fable 5.1, and 8.5 percent for GPT-6 Astra.
Not So Fast: The Fine Print
Before anyone crowns a champion, the caveats matter. DataCamp, which analysed the launch, notes that no third party had reproduced Google's benchmark table at launch. Independent results are mixed. Vals ranks Argon first among 41 models on its index at 68.9 percent, ahead of Opus 5.5 at 67.0 percent and Astra at 63.1 percent. But on the Artificial Analysis Intelligence Index, Argon scored 52.6, behind Opus 5.5 at 57.6 and just shy of Astra at 52.7.
Argon also lost some of the toughest coding contests. It scored 55.0 percent on FrontierSWE v2 against 65.5 percent for Astra, and 57.4 percent on Terminal-Bench 4.0 against 66.4 percent for Opus 5.5. Reports cited by DataCamp also describe a split on honesty: one analysis put Argon's hallucination rate at 15 percent against 51 percent for Astra, but its factual accuracy at 50 percent against 63 percent. Axios reported that Bloomberg said some Google staff found its performance lacking in internal testing, which Google disputed.
Google has also left questions open. It has not stated an input context window, has not published an API model ID, and has not said how long its introductory pricing will last.
The Price War
Money may be the real story. Argon's introductory price is $2 per million input tokens and $10 per million output tokens, rising to $4 and $20 later, with cached input discounted by 95 percent. By comparison, GPT-6 Astra lists at $10 and $50, and Claude Opus 5.5 at $4 and $20. Artificial Analysis measured the cost of running its index at $1.99 per average task for Argon, $3.26 for Astra and $5.98 for Opus 5.5, even though Argon used more tokens than the median model.
For businesses running thousands of automated tasks a day, those differences add up fast. They also explain why the rest of the industry is racing to respond.
Rivals Prepare to Strike Back
Fresh reports published on 20 October suggest the next round is imminent, though none of it is officially confirmed. According to TestingCatalog and Android Headlines, a researcher known as Lumina spotted Microsoft updating 18 evaluation configurations from GPT-5.6 Terra to GPT-6.1 Terra, the sort of back-end change that usually precedes a release. The Information has reported that OpenAI's new Terra model is meant to beat the current GPT-6.1 Sol, which costs $2 per million input tokens and $10 per million output tokens, while costing less.
Anthropic is also reportedly preparing an unreleased model that could launch under its Fable or Opus brand. Early testers say it is better at inferring what users want from vague instructions, and at spotting the underlying design flaw behind a software bug instead of patching the symptom. Google, meanwhile, is said to be readying Gemini 4 Carbon, an upgrade on Argon, with testing reportedly showing Google still leading in visual tasks such as video analysis and automated website testing.
Reporter Stephanie Palazzolo of The Information said October should be a busy month for new model releases, while cautioning that some launches could slip into November. OpenAI may also be testing a new image model, GPT-Image-3, and ChatGPT Slides has just gained real-time collaborative editing.
Expert Perspective: Benchmarks Are Not Reality
Security researchers have a clear message for anyone dazzled by the scoreboard. NeuralTrust, a security firm that analysed the launch, pointed out that several vendors can claim leadership on prompt-injection resistance without publishing scores, and that the sensible response is to build controls around any model rather than trust one. OWASP ranks prompt injection as the number one risk in its Top 10 for large language model applications.
There is a deeper point here too. Benchmarks are chosen, run and reported by the companies that stand to profit from them. A model that tops a leaderboard in September can look ordinary by Christmas, and the tests that matter most, like how well a model handles your messy real-world data, rarely appear in any table.
Google's recent history adds context. Its last flagship was the Gemini 3 series in November 2025, and reports in July and August described investor worries about a delayed Gemini 3.5 Pro, departures from its AI teams and a leadership shake-up. Argon looks like the comeback. Whether it holds up under public use is the test.
What This Means for You
For everyday users, the immediate effect is limited. You almost certainly cannot use Argon today, and the leaked rivals are not yet out. But the pattern is clear: the best models are getting cheaper, and the top spot changes hands within weeks. Expect the apps you use to get smarter and more capable of long, multi-step jobs, from drafting documents to testing websites.
For workers, the long-output and code-migration claims are a signal that AI is moving from answering questions to completing big projects. If your job involves repetitive software, legal or financial analysis, expect AI tools to take on larger chunks of the work, with humans checking the results.
For anyone who worries about online safety, Argon's rollout is a rare example of a company holding back a powerful model to give defenders a head start. Whether that approach is enough, and whether competitors follow it, will matter for everyone who uses the internet.
The Verdict
Argon is the most interesting model launch of the autumn, not because it has won, but because nobody can yet prove whether it has. Google has the numbers, the price and the headline-grabbing demos. OpenAI and Anthropic have the momentum of products already in people's hands, and by the look of this week's leaks, a response ready to go.
The next few weeks will settle it. When Argon, Terra, Anthropic's next model and Carbon are finally in the public's hands, the scoreboard will matter a lot less than the simplest test of all: which one do people actually choose to use? Until then, treat every big number with a pinch of salt, and keep your eyes on the release calendar.



